Understanding the Problem
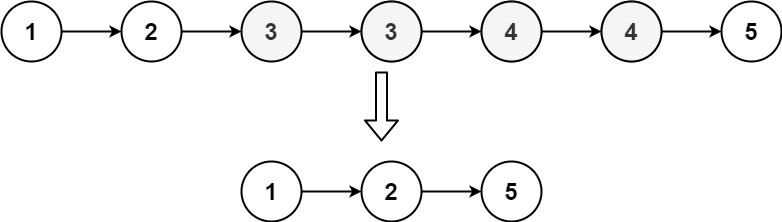
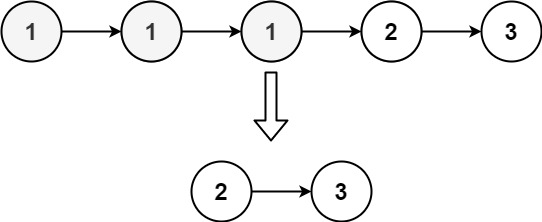
The core challenge of this problem is to remove all nodes that have duplicate values from a sorted linked list. The significance of this problem lies in its applications in data cleaning and preprocessing, where duplicates need to be removed to ensure data integrity. A common pitfall is to mistakenly remove only the duplicate nodes and not the original node that has duplicates.
Approach
To solve this problem, we need to traverse the linked list and identify nodes with duplicate values. A naive approach would involve nested loops, but this would be inefficient. Instead, we can use a single pass approach with a dummy node to handle edge cases more gracefully.
Naive Solution
The naive solution involves using nested loops to compare each node with every other node, which results in a time complexity of O(n^2). This is not optimal for larger lists.
Optimized Solution
An optimized solution involves using a single pass with a dummy node. The dummy node helps in handling edge cases where the head itself might be a duplicate. We maintain a pointer to the previous node and check for duplicates as we traverse the list.
Algorithm
Here is a step-by-step breakdown of the optimized algorithm:
- Create a dummy node and point its next to the head of the list.
- Initialize a pointer, `prev`, to the dummy node.
- Traverse the list with a pointer, `current`.
- For each node, check if it has a duplicate by comparing it with the next node.
- If duplicates are found, skip all nodes with the same value.
- Otherwise, move the `prev` pointer to the current node.
- Continue until the end of the list.
- Return the list starting from the dummy node's next.
Code Implementation
// Definition for singly-linked list.
struct ListNode {
    int val;
    ListNode *next;
    ListNode() : val(0), next(nullptr) {}
    ListNode(int x) : val(x), next(nullptr) {}
    ListNode(int x, ListNode *next) : val(x), next(next) {}
};

class Solution {
public:
    ListNode* deleteDuplicates(ListNode* head) {
        // Create a dummy node to handle edge cases
        ListNode* dummy = new ListNode(0, head);
        ListNode* prev = dummy; // Previous node pointer

        while (head != nullptr) {
            // Check if the current node has a duplicate
            if (head->next != nullptr && head->val == head->next->val) {
                // Skip all nodes with the same value
                while (head->next != nullptr && head->val == head->next->val) {
                    head = head->next;
                }
                // Link previous node to the node after the last duplicate
                prev->next = head->next;
            } else {
                // Move the previous node pointer
                prev = prev->next;
            }
            // Move to the next node
            head = head->next;
        }

        // Return the new head of the list
        return dummy->next;
    }
};
Complexity Analysis
The time complexity of the optimized solution is O(n), where n is the number of nodes in the list. This is because we traverse the list only once. The space complexity is O(1) as we are using a constant amount of extra space.
Edge Cases
Potential edge cases include:
- An empty list (head is nullptr).
- A list with all unique elements.
- A list where all elements are duplicates.
- A list with consecutive duplicates at the beginning or end.
Each of these cases is handled by the algorithm, ensuring robustness.
Testing
To test the solution comprehensively, consider the following test cases:
- head = [] (empty list)
- head = [1, 2, 3, 4, 5] (all unique elements)
- head = [1, 1, 1, 1, 1] (all elements are duplicates)
- head = [1, 1, 2, 3, 3] (consecutive duplicates at the beginning and end)
Using a testing framework like Google Test can help automate and validate these test cases.
Thinking and Problem-Solving Tips
When approaching such problems, consider the following tips:
- Understand the problem constraints and edge cases.
- Think about the data structure properties (e.g., sorted list) and how they can simplify the solution.
- Start with a naive solution and iteratively optimize it.
- Use dummy nodes to handle edge cases more gracefully.
Practice solving similar problems and study different algorithms to improve problem-solving skills.
Conclusion
In this blog post, we discussed how to remove duplicates from a sorted linked list using an optimized approach. We covered the problem definition, approach, algorithm, code implementation, complexity analysis, edge cases, and testing. Understanding and solving such problems is crucial for developing strong problem-solving skills in programming.
Additional Resources
For further reading and practice, consider the following resources: