
Remove Duplicates from Sorted Linked List in Python (Time Complexity: O(n))
Given the head of a sorted linked list, delete all nodes that have duplicate numbers, leaving only distinct numbers from the original list. Return the linked list sorted as well.
Example 1:
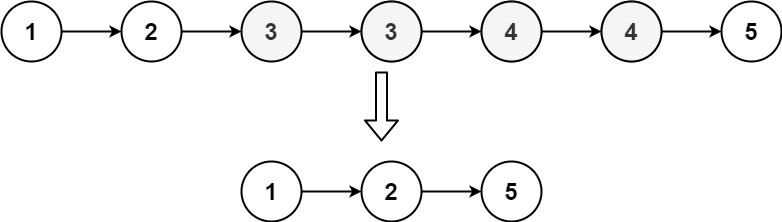
Input: head = [1,2,3,3,4,4,5]
Output: [1,2,5]
Example 2:
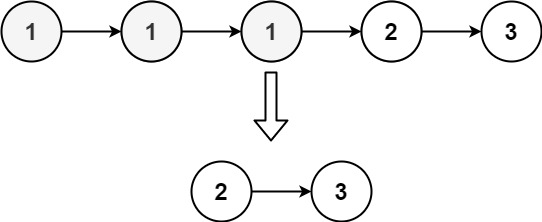
Input: head = [1,1,1,2,3]
Output: [2,3]
Constraints:
- The number of nodes in the list is in the range
[0, 300]. -100 <= Node.val <= 100- The list is guaranteed to be sorted in ascending order.
Understanding the Problem
The core challenge of this problem is to remove all nodes that have duplicate values from a sorted linked list, ensuring that only distinct values remain. This is significant in scenarios where data integrity and uniqueness are crucial, such as in database management or data processing pipelines.
Common pitfalls include not handling edge cases like an empty list or a list where all elements are duplicates. Misconceptions might arise from misunderstanding the requirement to remove all instances of duplicates, not just one.
Approach
To solve this problem, we need to traverse the linked list and identify nodes with duplicate values. A naive solution might involve multiple passes through the list, but this would be inefficient. Instead, we can use a single pass with a dummy node to simplify edge cases.
Here’s a step-by-step approach:
- Create a dummy node that points to the head of the list.
- Use two pointers: one (prev) to track the last node before the sequence of duplicates, and another (current) to traverse the list.
- When duplicates are found, skip all nodes with the duplicate value.
- Adjust pointers to remove the duplicates from the list.
Algorithm
Here’s a detailed breakdown of the algorithm:
- Initialize a dummy node and set its next pointer to the head of the list.
- Set prev to the dummy node and current to the head of the list.
- While current is not null:
- If current has a duplicate (current.next is not null and current.val == current.next.val):
- Skip all nodes with the duplicate value.
- Set prev.next to the node after the last duplicate.
- Else, move prev to current.
- Move current to the next node.
- If current has a duplicate (current.next is not null and current.val == current.next.val):
- Return dummy.next as the new head of the list.
Code Implementation
class ListNode:
    def __init__(self, val=0, next=None):
        self.val = val
        self.next = next

def deleteDuplicates(head):
    # Create a dummy node to handle edge cases easily
    dummy = ListNode(0)
    dummy.next = head
    prev = dummy
    current = head

    while current:
        # Check if current node is a duplicate
        if current.next and current.val == current.next.val:
            # Skip all nodes with the same value
            while current.next and current.val == current.next.val:
                current = current.next
            # Link prev node to the node after the last duplicate
            prev.next = current.next
        else:
            # Move prev to current if no duplicate
            prev = current
        # Move current to the next node
        current = current.next

    return dummy.next
Complexity Analysis
The time complexity of this approach is O(n), where n is the number of nodes in the linked list. This is because we traverse the list only once. The space complexity is O(1) as we are using a constant amount of extra space.
Edge Cases
Consider the following edge cases:
- An empty list: The function should return an empty list.
- A list with all duplicate values: The function should return an empty list.
- A list with no duplicates: The function should return the original list.
Examples:
Input: head = []
Output: []

Input: head = [1,1,1]
Output: []

Input: head = [1,2,3]
Output: [1,2,3]
Testing
To test the solution comprehensively, consider using a variety of test cases, including simple, complex, and edge cases. Python’s unittest framework can be used for this purpose.
import unittest

class TestDeleteDuplicates(unittest.TestCase):
    def list_to_linkedlist(self, elements):
        dummy = ListNode(0)
        current = dummy
        for element in elements:
            current.next = ListNode(element)
            current = current.next
        return dummy.next

    def linkedlist_to_list(self, head):
        elements = []
        while head:
            elements.append(head.val)
            head = head.next
        return elements

    def test_deleteDuplicates(self):
        test_cases = [
            ([1,2,3,3,4,4,5], [1,2,5]),
            ([1,1,1,2,3], [2,3]),
            ([], []),
            ([1,1,1], []),
            ([1,2,3], [1,2,3])
        ]
        for input_list, expected_output in test_cases:
            head = self.list_to_linkedlist(input_list)
            new_head = deleteDuplicates(head)
            self.assertEqual(self.linkedlist_to_list(new_head), expected_output)

if __name__ == '__main__':
    unittest.main()
Thinking and Problem-Solving Tips
When approaching such problems, it’s essential to:
- Understand the problem requirements and constraints thoroughly.
- Break down the problem into smaller, manageable parts.
- Consider edge cases and how your solution handles them.
- Practice similar problems to improve problem-solving skills.
Conclusion
In this blog post, we discussed how to remove duplicates from a sorted linked list efficiently. We covered the problem definition, approach, algorithm, code implementation, complexity analysis, edge cases, and testing. Understanding and solving such problems is crucial for developing strong problem-solving skills in programming.
Additional Resources
For further reading and practice, consider the following resources: